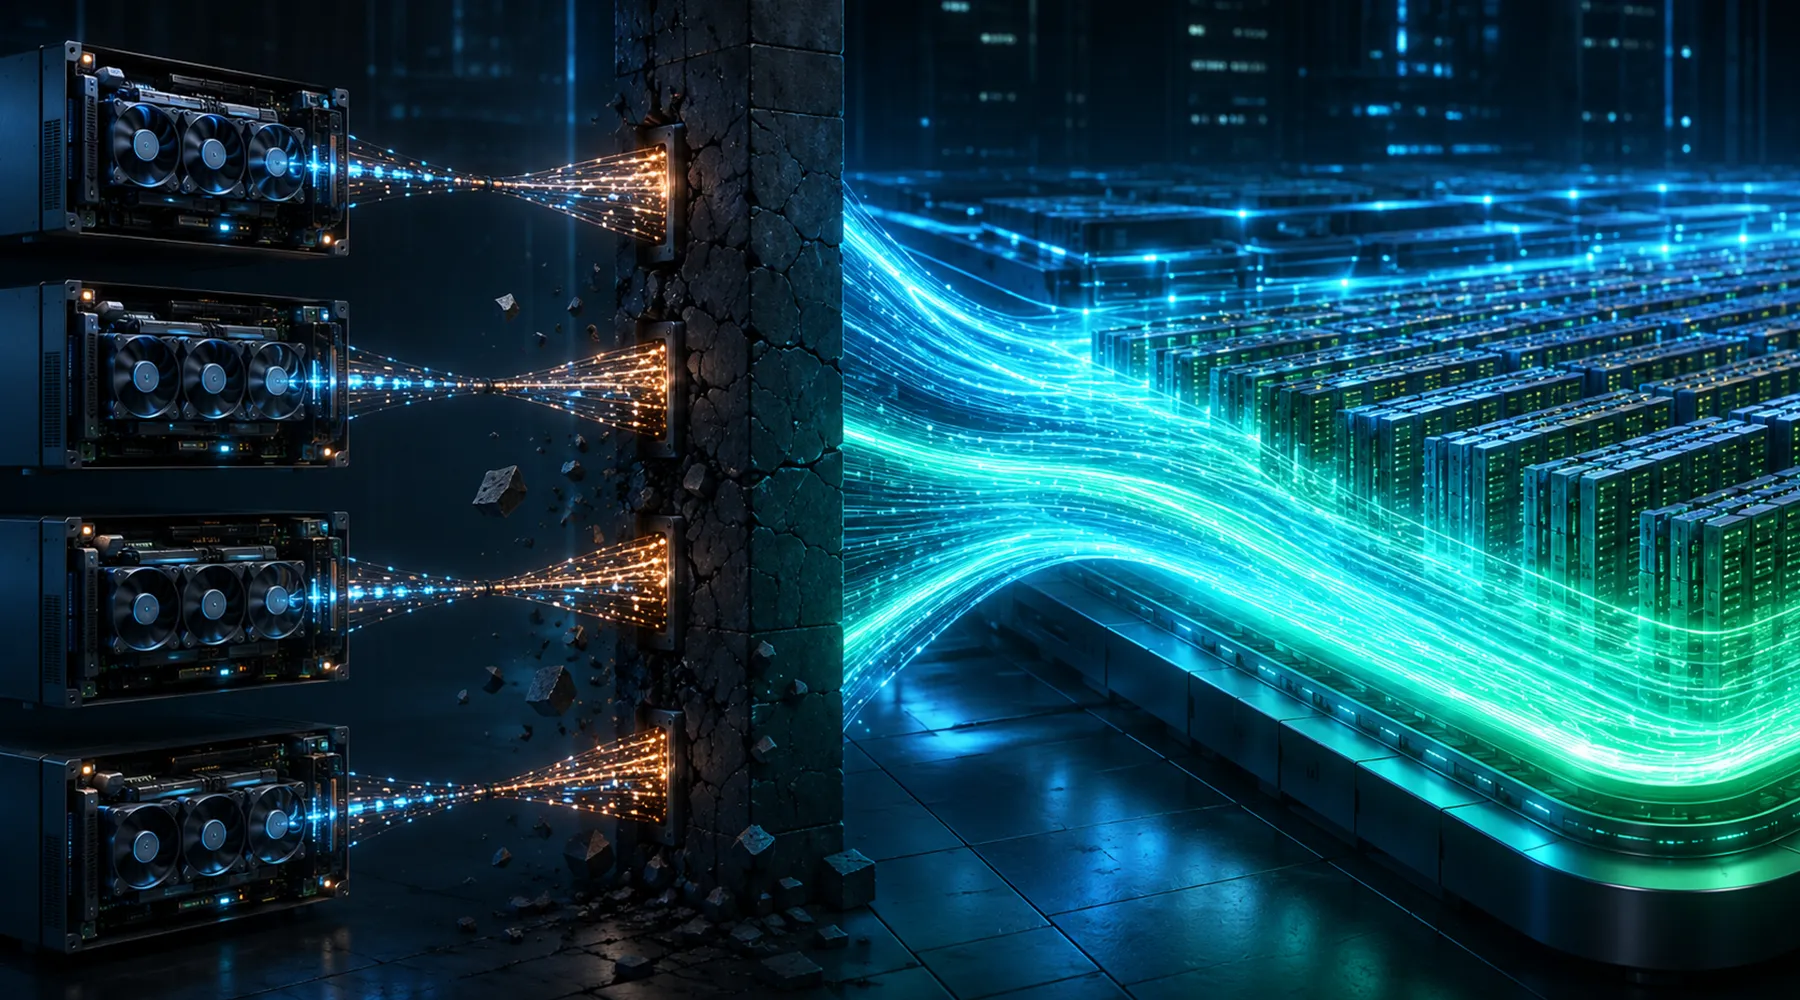

Limit innovation or rethink how you manage Memory and GPUs?

Always-on AI and agentic workloads make demand and costs increasingly difficult to predict.
Up to 8x GPU generations for every server lifecycle.

Physically locked to individual servers, unable to be shared or reallocated.
AI inference models demand 3–5x more memory than servers support.

Demand is growing faster than new generation capacity can be added.
AI demand is competing for limited supplies of GPUs, HBM and DRAM.
Own the infrastructure that produces your AI tokens. Control cost, performance, capacity and data security.
LIQID combines purpose-built hardware and Matrix software to deliver dynamic memory and GPU capacity for more tokens per watt and dollar.


AI Inference workloads are creating unprecedented opportunities, but also new challenges. How can we help you get the most from your AI?
Stop assigning GPUs to servers. Assign them to jobs. Allocate from a shared pool per job, per tenant, per hour — through the scheduler you already run — and take them back when the job ends. Utilization goes up without buying anything.
LIQID pools up to 30 GPUs to one host or shared across hosts for maximum performance and agility.
Learn Moreabout LIQID GPU Pooling SolutionsSize the prefill pool to the burst, then release it. The same GPUs go back to serving other work in seconds instead of waiting for the next spike.
LIQID pools up to 30 GPUs to one host or shared across hosts for maximum performance and agility.
Learn Moreabout LIQID UltraStack AMD MI350PPool the GPUs the job needs, run it, then unbuild it. No purpose-built system sitting idle between jobs.
LIQID pools up to 30 GPUs to one host or shared across hosts for maximum performance and agility.
Learn Moreabout LIQID UltraStack AMD MI350PPut a real DRAM tier between the HBM you can't source and the NVMe that's too slow to backstop it. More concurrent sessions per GPU, longer context, and no extra HBM to go find.
CXL 2.0 DRAM fabric — upto 100TB to a single host or shared across 16 nodes.
Learn Moreabout LIQID Memory Pooling SolutionsGive the memory to the node running the job, for as long as the job runs, then take it back. No new server, no new fabric for your team to learn.
CXL 2.0 DRAM fabric — up to 100TB to a single host or shared across 16 nodes.
Learn Moreabout LIQID Memory Pooling SolutionsOne pool, sized for the peak of the sum. In-memory databases, feature stores and analytics draw what they need from it and give it back — without a per-node hardware refresh.
CXL 2.0 DRAM fabric — up to 100TB to a single host or shared across 16 nodes.
Learn Moreabout LIQID Memory Pooling SolutionsBoth fabrics in one system under one control plane. Relieve each constraint from its own pool, so neither one forces you to over-buy the other.
Both fabrics, one control plane. Compose GPU-to-memory ratios per workload, then hand them back.
Learn Moreabout LIQID AbacoPool different GPU-to-memory ratio for each phase, out of the same hardware, and change it when the traffic shape changes.
Both fabrics, one control plane. Compose GPU-to-memory ratios per workload, then hand them back.
Learn Moreabout LIQID AbacoBuild the machine the job needs out of pooled GPU and pooled memory, then unbuild it and give the parts back to everything else.
Both fabrics, one control plane. Compose GPU-to-memory ratios per workload, then hand them back.
Learn Moreabout LIQID AbacoDeliver high throughput and lower latency for LLM and generative AI workloads.
Mission-ready AI Infrastructure with Better GPU and Memory Economics
Composing Smarter Financial Services
AI inference models demand 3–5x more than servers support.
Composing Creativity, Content, and Experiences - Composable Infrastructure in Media and Entertainment
LIQID Memory and GPU Pooling for Neoclouds and Cloud Service Providers




AI Inference workloads are creating unprecedented opportunities, but also new challenges. How can we help you get the most tokens and ROI from your AI?
Request a Demo